The brain behind every answer
Dunefox’s RAG-powered AI engine retrieves from your approved content before generating a response. If the required information is not available, the conversation can be handed to your team instead of relying on a guessed answer.
Built for enterprise-grade accuracy and speed
Every component of Dunefox AI Engine is optimized to deliver grounded, accurate, and instant responses.
Retrieves facts before it generates answers
Unlike standard LLMs that guess, Dunefox first searches your private knowledge base for semantically relevant chunks, then passes that context into the model. Every answer is grounded in your truth.
Fast retrieval and streamed answers
Dunefox is engineered for speed. From vector index lookup to response streaming, queries are resolved in real time, keeping your web visitors and WhatsApp customers engaged without delay.
Remembers context across the entire conversation
Dunefox retains complete thread memory and user state across multiple turns. It remembers user preferences, order numbers, and previous questions without asking twice.
5-stage RAG pipeline architecture
How Dunefox ingests questions, searches your knowledge vectors, and produces answers grounded in approved content.
User Query
A customer question arrives from WhatsApp, web chat, social messaging, or a Dunefox Voice call.
Multi-channel ingestionEmbedding
The query is converted to a high-dimensional vector using a best-in-class embedding model.
Semantic representationVector Retrieval
Cosine similarity search finds the K most semantically relevant chunks from your private knowledge base.
Top-K semantic searchContext Injection
Retrieved chunks are injected into the LLM prompt as grounding context, bounding the model to only your data.
Prompt augmentationGrounded Answer
The LLM generates a precise response using only verified facts, eliminating hallucination entirely.
Knowledge-grounded output Voice
How conversational AI becomes an AI voice agent
Dunefox Voice extends the Dunefox AI engine to phone calls. Caller speech enters the conversational AI workflow, approved knowledge is retrieved, and the response returns as natural speech with the conversation context intact.
- Understand caller intent from natural speech
- Retrieve approved business knowledge
- Generate a grounded response
- Return the answer through the selected voice stack
Connects to your tools. Protects your data
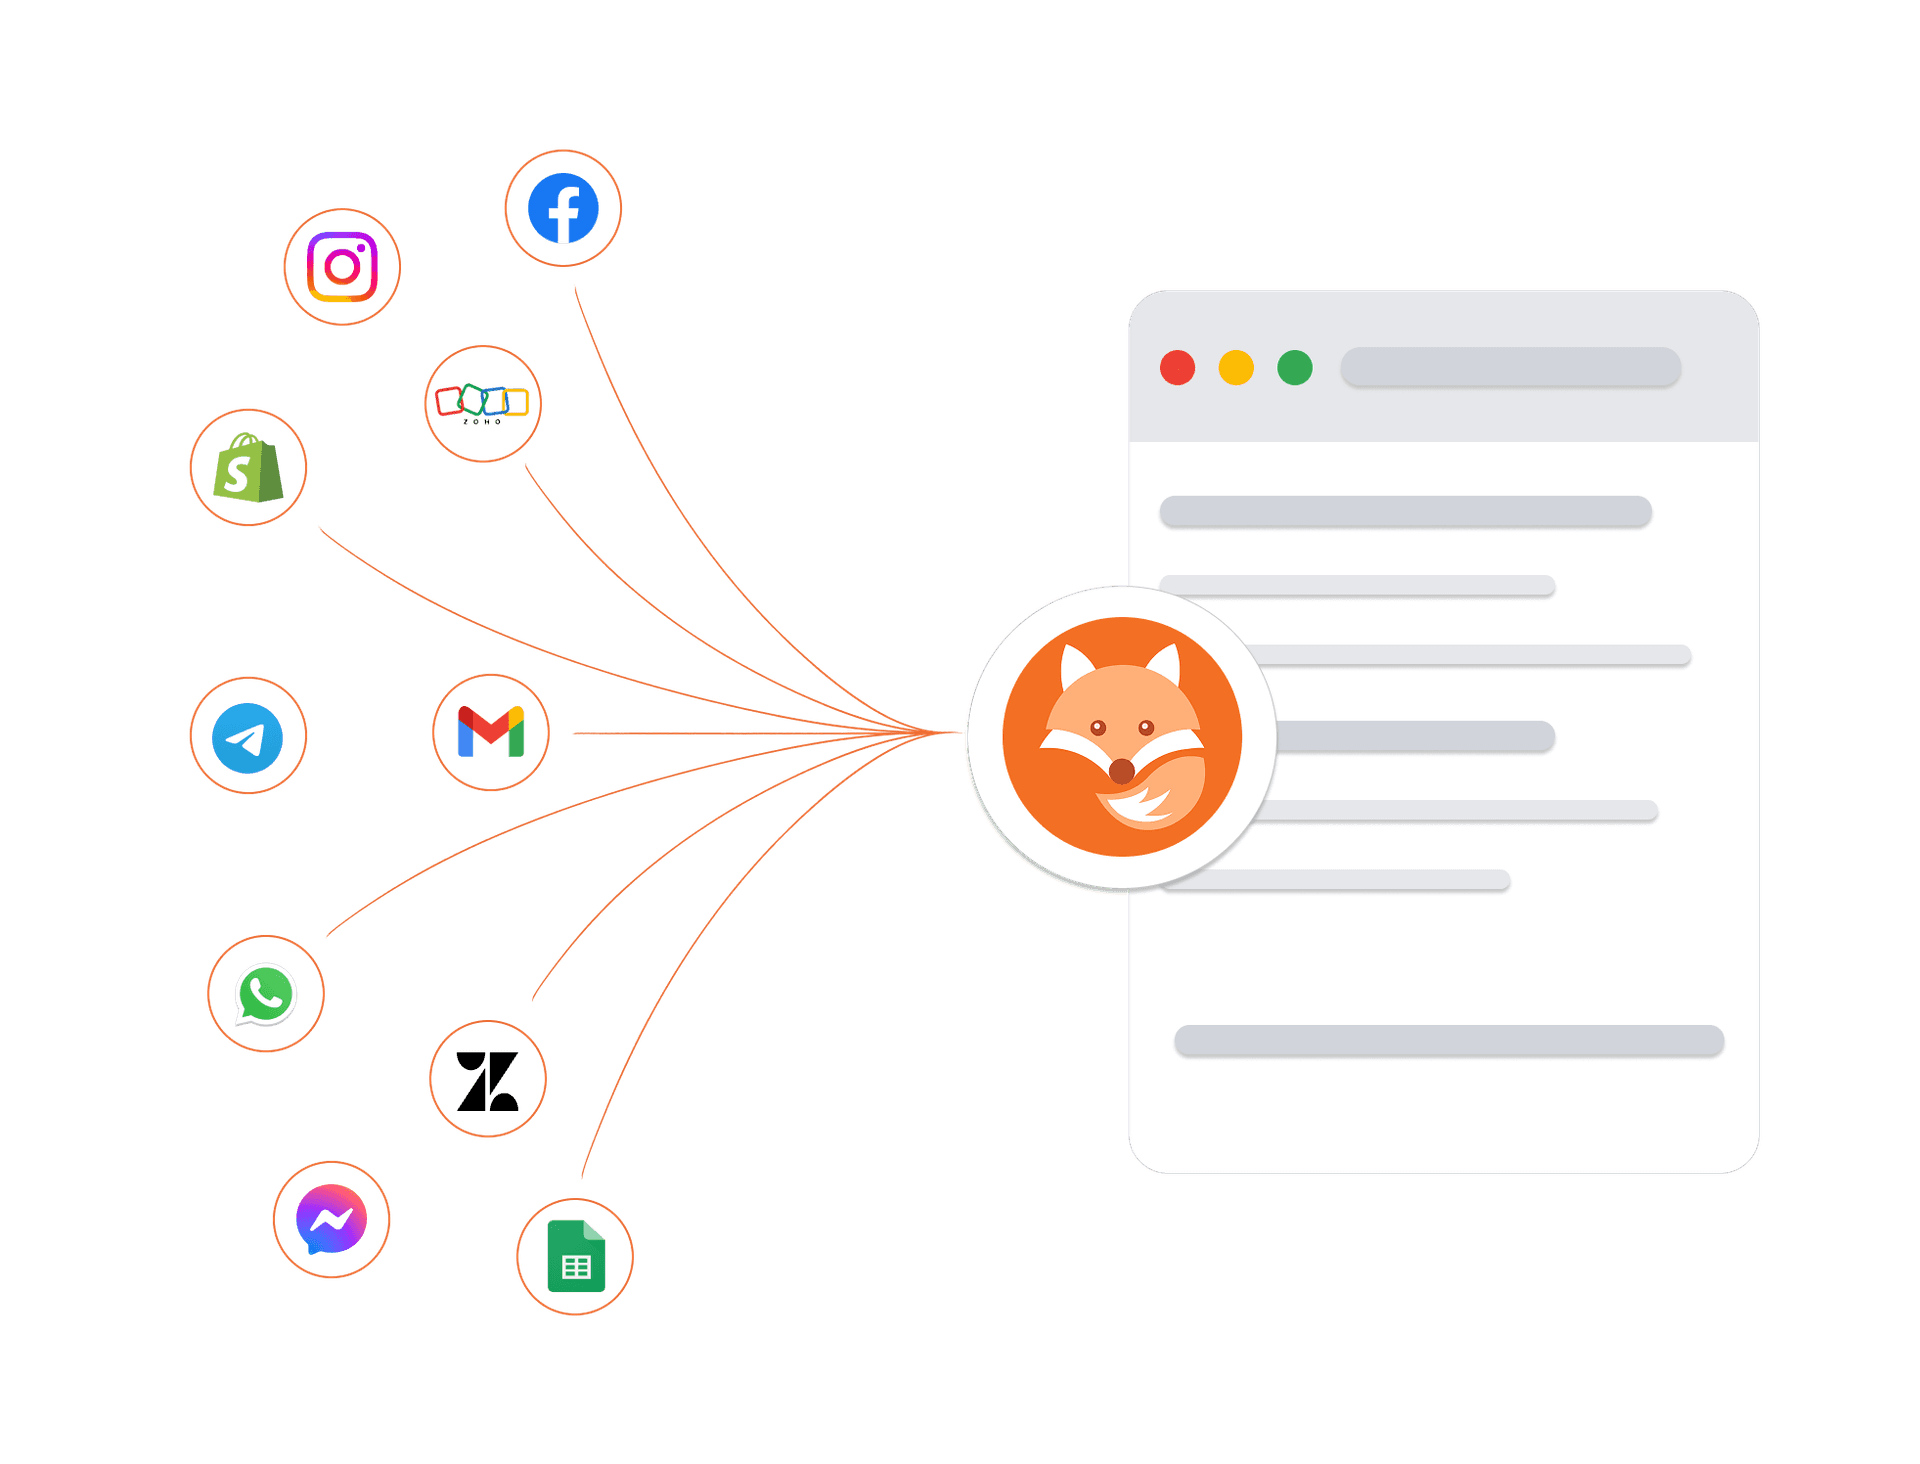
Connect your existing tools, including telephony providers for AI voice calling, and trust that every customer conversation is protected by enterprise-grade security architecture.
Encrypted in transit and at rest
Every conversation and customer record is protected at every layer.
Enterprise isolation
Your data is strictly sandboxed per workspace.
High-availability infrastructure
Built on managed cloud infrastructure with monitoring and backups.
GDPR-ready controls
Data export and deletion workflows are available.
Frequently asked questions about Dunefox AI Engine
How does Dunefox AI Engine prevent hallucinations?
Dunefox uses a Retrieval-Augmented Generation (RAG) architecture. Before generating an answer, it performs semantic vector search over your uploaded documents, websites, and FAQs. The retrieved facts are injected into the prompt as grounding context, forcing the AI to answer strictly using your verified data.
How does Dunefox handle data security and privacy?
Data ingested into the Dunefox AI Engine is encrypted in transit and at rest. Knowledge bases and conversation records are isolated to the relevant workspace and are not used to train public AI models.
What languages does the AI Engine support?
The AI engine natively supports over 50 languages including English, Hindi, Spanish, French, German, Arabic, Portuguese, and Hinglish with auto-detection and real-time translation.
How fast is the average response time?
Dunefox uses indexed knowledge retrieval and streams answers as they are generated. Actual response time depends on the connected channel, model provider, knowledge source, and network conditions.
Put the most advanced AI engine to work for your business
Bring conversational AI tools and conversational AI for customer support into one grounded workflow with fast retrieval and human handoff.
14 days free. All Fox Pro features. No card required.